Shadow-Mode Jev Before It Skips Your CI Tests
AI CI test selection with Jev starts in shadow: count false skips against real failures, canary on a slice, and pin the action by SHA before you enforce.

Go deeper. Build your own.
At 21:36 UTC on Sep 20, a small community GitHub Action for AI CI test selection merged a pull request that changed one default in its action.yml: the mode input went from shadow to enforce, and ninety-one minutes later the maintainer tagged v0.1.0. The repo’s one-line description still promises “shadow mode by default”. The action has two stars, so nobody’s pipeline is on fire. Treat it as a preview: young classifier tools will move their defaults faster than you read their READMEs, and here the default that moved is the one that decides whether your tests run.
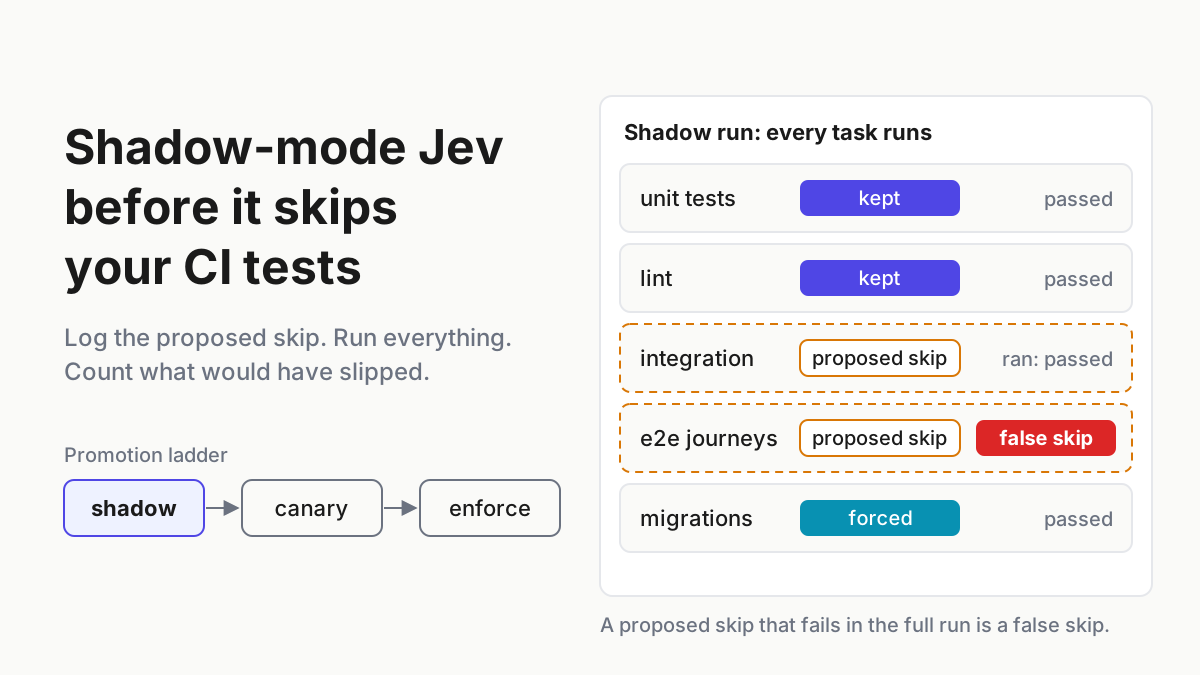
The move this piece teaches is a promotion ladder for any classifier that can skip CI work. By Tuesday your selector runs in shadow: it proposes skips, and you run everything anyway. You have a written definition of a false skip, a budget set before you see data, a weekly review of every disagreement, a rollback trigger that flips a repository variable, and the action pinned to a commit SHA with every input set by hand. Enforce is something the selector earns, one rung at a time.
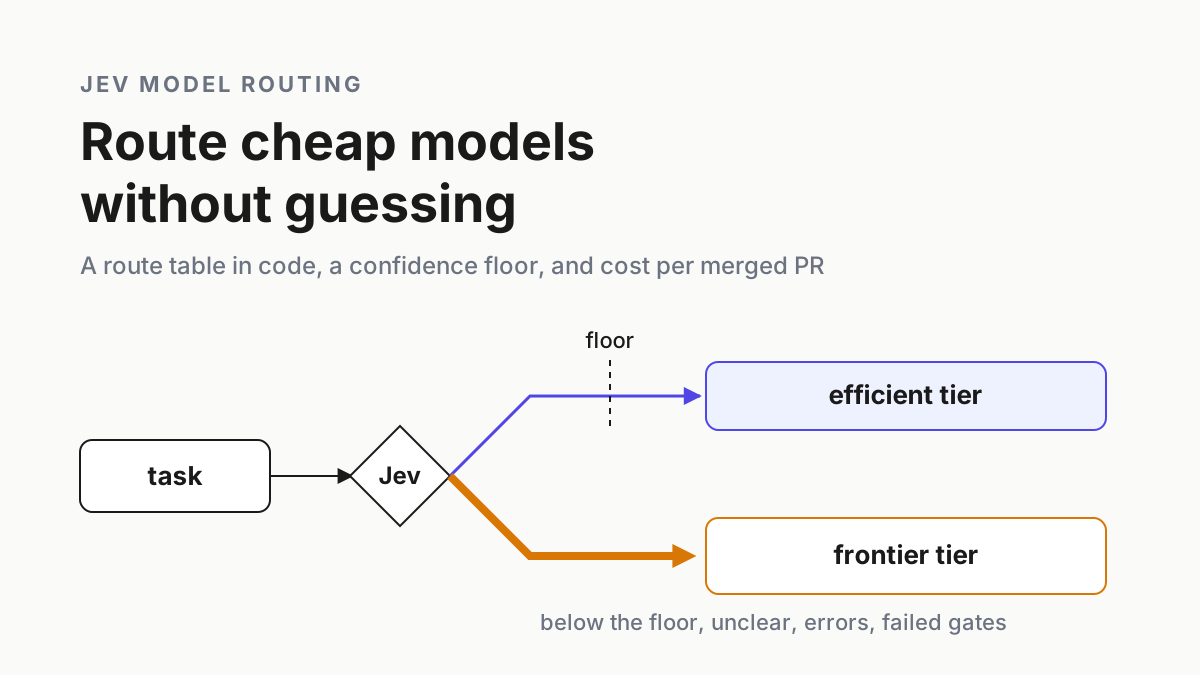
The pressure to skip is honest. Agents open pull requests around the clock, each one pays for the full suite, and a decision model priced at $0.042 per million input tokens looks like a cheap way to cut the bill. But a skipped test leaves nothing behind. The only way to learn what a skip cost is to run the test anyway and compare, which is all shadow mode is.
Sep 20: jev-ci-selector moved its default to enforce ninety minutes before v0.1.0
guilhem/jev-ci-selector went up on Sep 19 as an MIT-licensed MVP. You hand it a mapping of CI tasks, it asks TypeSafe’s Jev about the pull request, and it emits outputs your test jobs can gate on. Its repo description reads, in full: “Conservative CI task selection for GitHub Actions with Jev, a pure policy engine, and shadow mode by default.”
Then the weekend happened.
| Time (UTC) | What changed |
|---|---|
| Sep 19, 19:55 | Repo created with the MVP commit |
| Sep 20, 18:31 | PR #3 merges a synthetic, replayable Jev evaluation corpus |
| Sep 20, 21:36 | PR #4 merges (commit c76225d): mode default shadow → enforce; adds skip-below (default 0.05) and model (default jev-1.13.0) |
| Sep 20, 23:07 | Tag v0.1.0 on commit 4849690b |
| Sep 20, 23:09 | Release published |
| Sep 21, 13:54 | main sits six commits past the tag; the description still says shadow by default |
PR #4 rewrote the API. It replaced the old config catalog input with a required inline tasks input, and its body says “selection defaults to enforce (shadow remains explicit)”. Its own validation list ends: “No new live-provider qualification, merge or release tag is included.” The action.yml at the tag and the action.yml on main agree on the two inputs that matter here: mode defaults to enforce, skip-below to '0.05'.
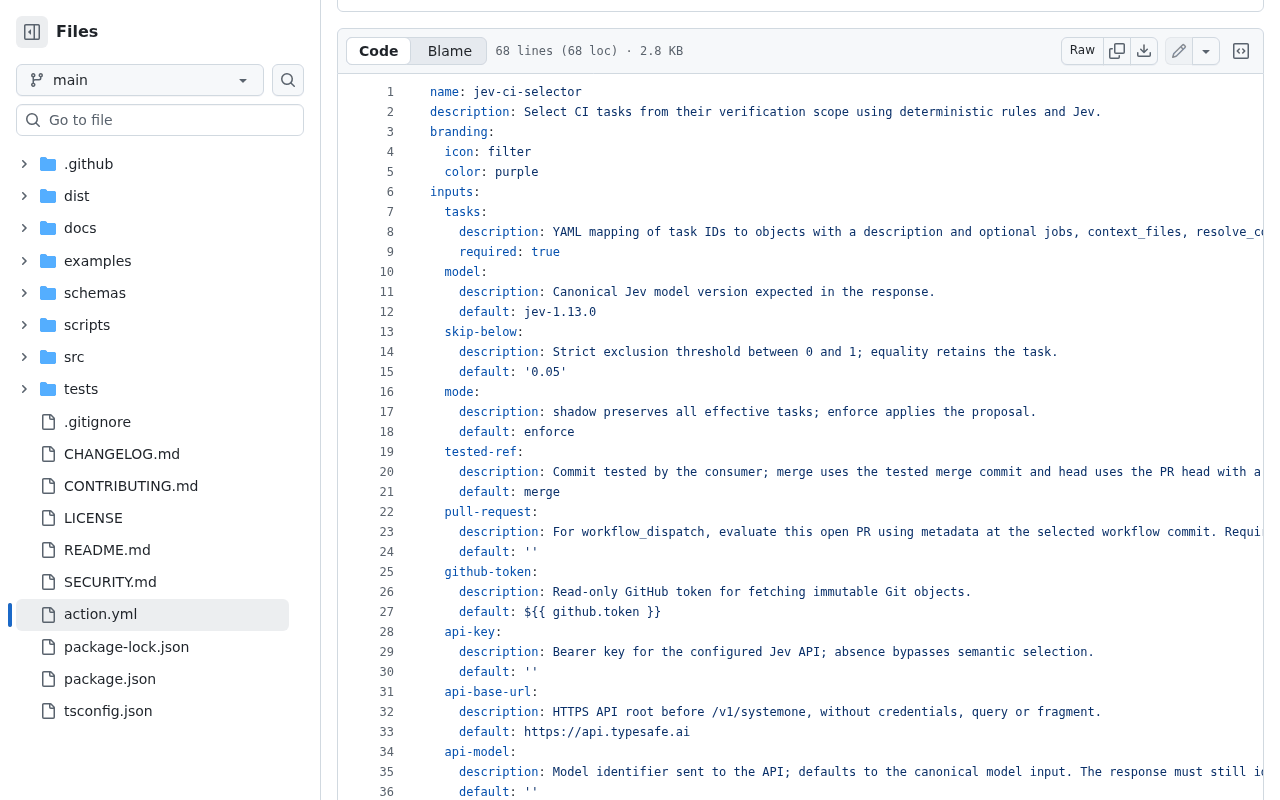 Screenshot: GitHub, “jev-ci-selector/action.yml at main · guilhem/jev-ci-selector · GitHub” (main branch, Sep 21, 2026), captured Sep 21, 2026.
The README’s closing note gives the trap its shape: “This API is a breaking update: existing integrations must supply inline tasks; explicitly set mode: shadow to retain observation-only behavior.” Anyone who wired the action in against main on Saturday had to rewrite the integration, and the obvious rewrite, adding tasks, lands in enforce unless it also carries that one line. The API change was the visible part. The default riding along with it was the part that skips tests.
The maintainer is candid about the rest. The README says “A false output is a policy decision, not a guarantee that the task cannot detect a regression. The default threshold 0.05 is experimental.” The shipped corpus is synthetic, no false-skip rate on a real repository is published, and the repo does not say why the default moved. Normal for a two-day-old tool, and exactly why the measurement has to be yours.
The same evening, at 22:43 UTC, an unrelated team opened the counter-example. Nine-Minds’ alga-psa, an open source MSP PSA, proposed shadow-mode Jev test selection across 306 integration suites and 41 browser journeys, summarized in one line: “Nothing changes which tests run yet.” It is an open pull request, not a result, and it does not use jev-ci-selector. Its design is the first rung of the ladder below.
A skipped test leaves no evidence, so the rollout has to manufacture it
Most gates leave a trace when they are wrong. A tool-call gate that allows a bad write leaves the write. A test selector that wrongly skips a suite leaves a green check beside a job that never ran, and the failure it would have caught ships with the next deploy. Without a comparison run you cannot tell a good skip from a lucky one.
This is a different job from regression gates for agent evals, which score the agent’s output inside CI. Here the thing under test is the classifier deciding which checks run at all. If you have run a staged rollout for evals, the rungs will look familiar.
Agents sharpen the stakes. A coding agent retrying against a CI that skips the suite it keeps breaking will converge on green without fixing anything. Fix-loop guards stop the retries; an honest selector keeps the green meaningful.
The ladder for AI CI test selection: shadow, canary, enforce
Three rungs, each with an exit condition written before you start.
- Shadow. The selector proposes; every task runs; each proposal is logged beside each task’s real result. The only rung where false skips are measured exactly, because nothing was skipped.
- Canary. A slice of pull requests runs in enforce, the rest stays in shadow, and a post-merge full run catches what the slice skipped. The slice tests plumbing, not accuracy.
- Enforce. Skips are real, and a permanent shadow holdback keeps the measurement running.
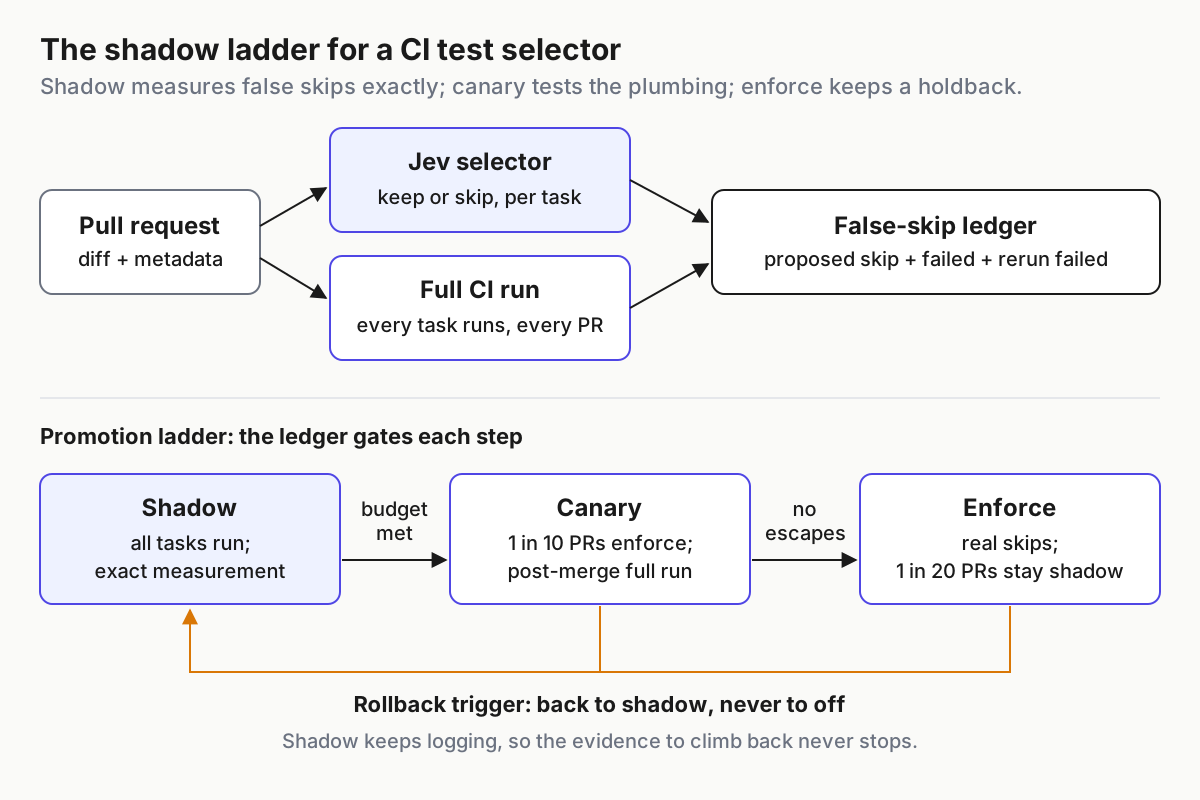 Shadow measures, canary tests the plumbing, enforce keeps a holdback. Every rollback goes to shadow, never to off.
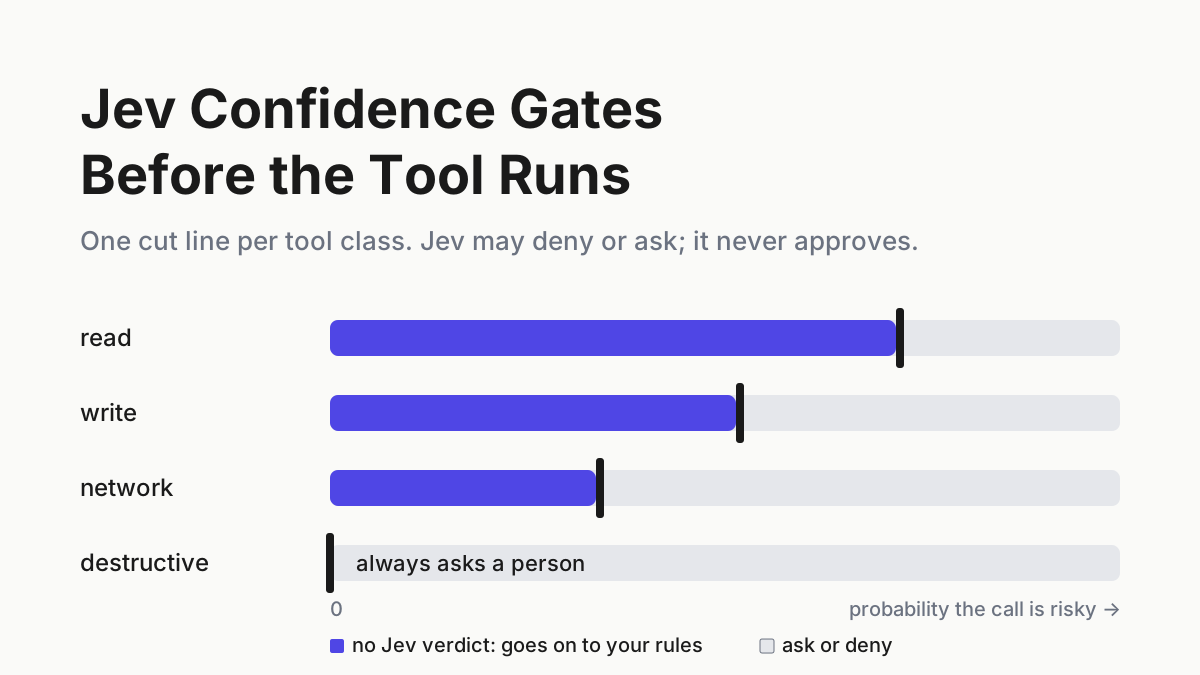
The ladder is not specific to CI. The same three rungs promote a per-tool-class confidence table for tool calls; only the counterfactual changes.
Step 1: Set the mode yourself and pin the action by commit SHA
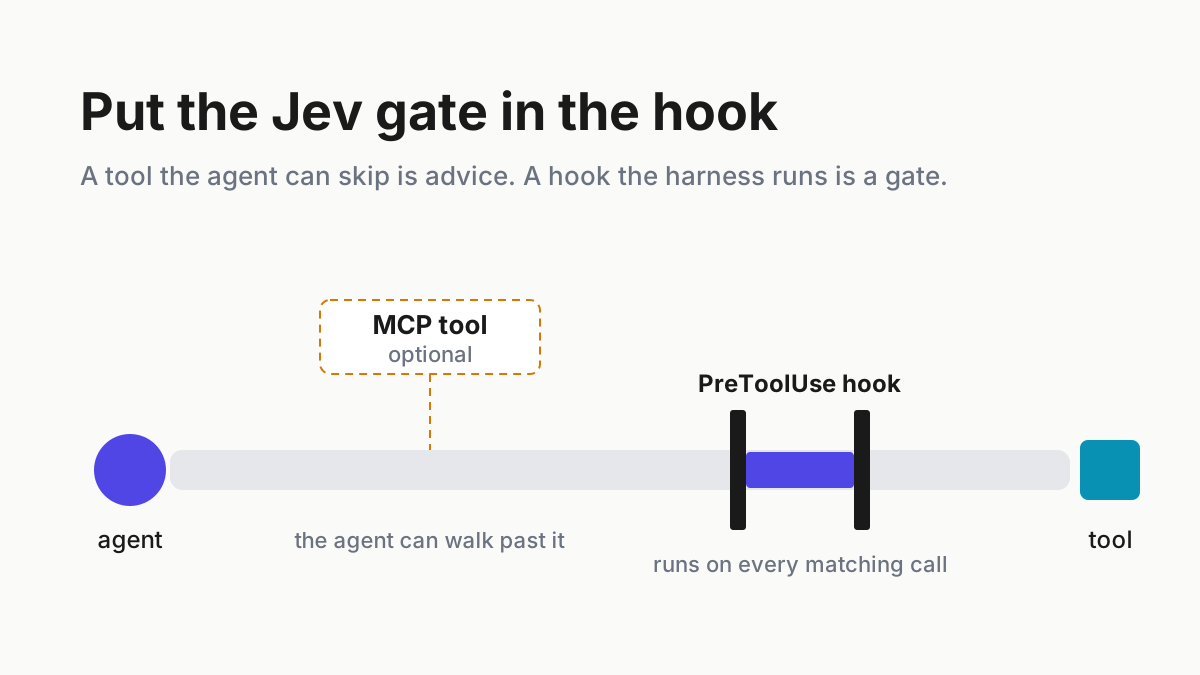
You need two defenses against a flipped default, and they cover different failures. Pin the action to the full commit SHA, which the README itself recommends: “Use the released commit SHA for immutable pinning.” A tag can move; a SHA cannot. Then set every behaviour-changing input explicitly, even where your value matches today’s default, so the next bump cannot change what runs without changing your file.
# .github/workflows/ci.yml (illustrative shape; check input names at your pinned SHA)
jobs:
  select:
    runs-on: ubuntu-latest
    steps:
      - id: stage
        env:
          PR: ${{ github.event.pull_request.number }}
          STAGE: ${{ vars.JEV_SELECTOR_STAGE }}   # shadow | canary | enforce; unset = shadow
        run: |
          case "$STAGE" in
            enforce) if [ $((PR % 20)) -eq 7 ]; then m=shadow; else m=enforce; fi ;;  # 1-in-20 holdback
            canary)  if [ $((PR % 10)) -eq 0 ]; then m=enforce; else m=shadow; fi ;;  # 1-in-10 slice
            *)       m=shadow ;;
          esac
          echo "mode=$m" >> "$GITHUB_OUTPUT"
      - id: jev
        uses: guilhem/jev-ci-selector@4849690b3ae2f185ce92024d6150a883656b2a9f   # v0.1.0
        with:
          mode: ${{ steps.stage.outputs.mode }}   # never inherit the action's default
          skip-below: '0.05'                      # explicit, even though it matches today
          model: jev-1.13.0                       # a versioned ID, never an alias
          allow-external-context: 'true'          # a data decision, made on purpose
          timeout-ms: '10000'
          api-key: ${{ secrets.TYPESAFE_API_KEY }}
          tasks: |
            integration:
              description: Integration suites for billing, invoicing and tenant setup
            e2e:
              description: Browser journeys through signup, checkout and account settings
Three details carry the lesson. The stage lives in a repository variable, so rollback is a settings change anyone on call can make in a minute; a pull request would itself have to pass CI first. An unset variable means shadow: you chose the safe default instead of inheriting someone else’s. And allow-external-context is spelled out because it defaults to 'false': “Explicit permission to send the diff and metadata to the configured API.”
Shadow still sends real diffs to a third party, so settle the repository’s data class before the first shadow run.
Pin the model the same way. TypeSafe’s models page warns that “An alias moves when a new release ships, so the answers behind it can change without a change on your side”, and advises pinning the versioned ID once thresholds are tuned against it.
On every bump of the pinned SHA, diff action.yml and the README between the old and new commit before merging the bump. Any change to a default, an input’s meaning or the task schema sends the repository back to shadow.
Step 2: Define a false skip counterfactually, and log what the join needs
Write the definition down in these words: a false skip is a task the selector proposed to skip that then failed in the full run on the same commit, and failed again on rerun. The rerun clause keeps flaky failures out of the count. Tasks that failed because the build broke upstream count once per pull request, not once per task.
The action exposes what the join needs: tested-ref defaults to the merge commit and a tested-sha output names the commit that was evaluated, a status output reads planned, bypassed or fallback, and a report-path output points at the selector’s report. Log one row per pull request and task.
| Field | Why it is there |
|---|---|
pr, tested_sha, task |
The join key against real task results |
stage, mode, action_sha |
Which rung and which code produced the proposal |
answer, skip_below, proposed |
The raw answer, not just the bit, so any threshold can be replayed offline |
model_reported |
The Jev version that actually answered |
status |
planned, bypassed or fallback; the last two are not proposals |
full_run, rerun, verdict |
Result, rerun result, and the review’s call: real miss, flake or infra |
Keep the raw answer. With it the weekly review can ask what 0.02 or 0.10 would have done without calling Jev again. Replaying a logged answer and re-querying the model carry different guarantees; the Jev decision log covers that split.
-- false skips measured in shadow this week (illustrative schema)
SELECT p.pr, p.task, p.answer, r.full_run, r.rerun
FROM proposals p
JOIN task_results r
ON r.tested_sha = p.tested_sha AND r.task = p.task
WHERE p.mode = 'shadow'
AND p.proposed = 'skip'
AND r.full_run = 'failure'
AND r.rerun = 'failure';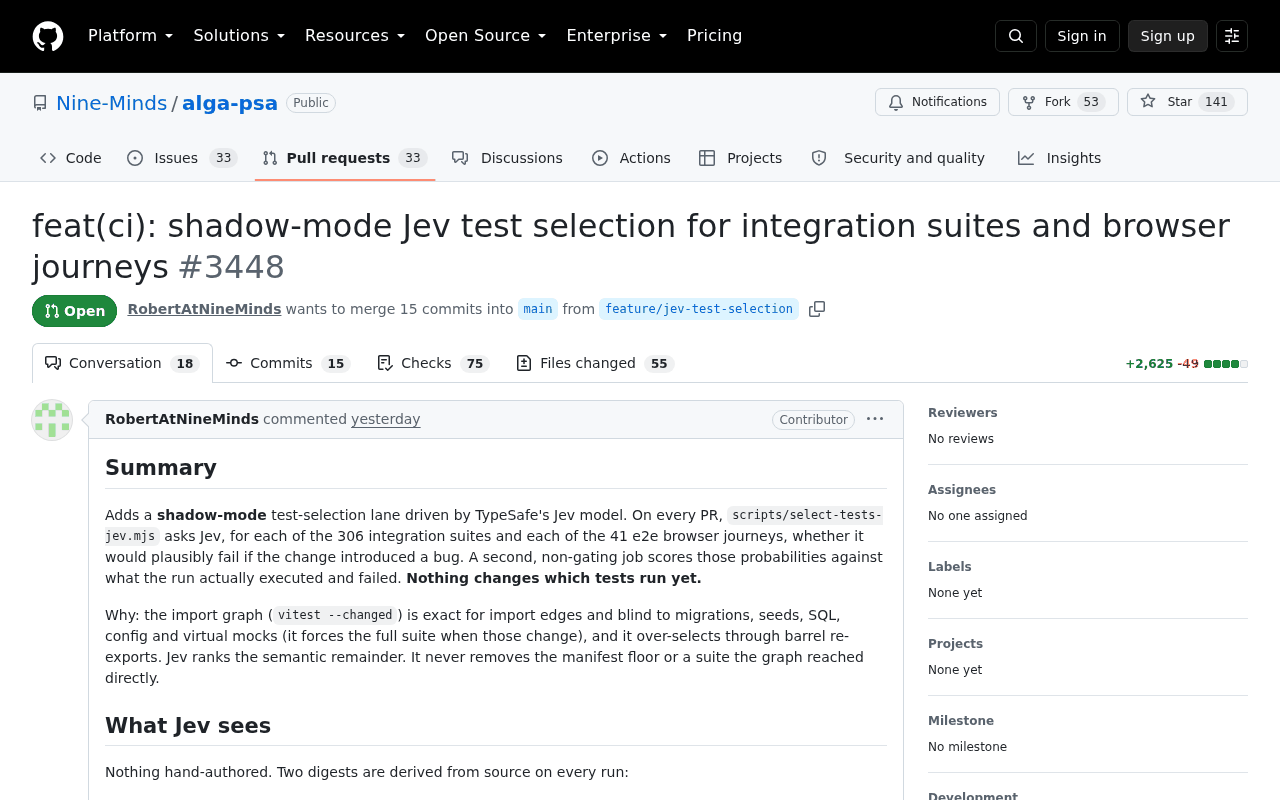 Screenshot: GitHub, “feat(ci): shadow-mode Jev test selection for integration suites and browser journeys” (opened Sep 20, 2026), captured Sep 21, 2026.
The alga-psa pull request shows the join done with care. A second, “non-gating job scores those probabilities against what the run actually executed and failed”, and its artifact reports “recall against real failures and deferred share at thresholds 0.3 / 0.5 / 0.7, listing every failure Jev would have deferred”. Two numbers per threshold, misses and savings: the two axes of your budget.
Step 3: Write the false-skip budget before you look at the data
A budget written after the first dashboard is a description of the dashboard. Write it first, per tier, with the evidence floor that has to be met before anyone reads the rate.
# selector-budget.yaml (illustrative numbers; set yours before shadow starts)
tiers:
  forced:                          # never listed in `tasks`: these jobs always run
    tasks: [migrations, security-scan, release-packaging]
  standard:
    max_miss_rate_bound: 0.02      # one-sided 95% upper bound, rolling window
    min_failures_observed: 150
  cheap:
    max_miss_rate_bound: 0.05
    min_failures_observed: 60
savings_floor:
  min_deferred_share: 0.20         # below this, enforce is not worth the risk
max_fallback_share: 0.05           # bypassed + fallback runs / all selector runs
The forced tier is the wall behind the gate. Tasks that guard what no other suite catches (migrations, security scans, the packaging step) are never handed to the selector, and their jobs run unconditionally. A classifier cannot skip what it is never asked about.
Measure the miss rate against failures, not pull requests: false skips divided by real task failures in the window, which is one minus the recall alga-psa reports. Vercel’s note on Jev thresholds says it directly: “Record the denominator when reporting accuracy.” A selector in a week with no failures has a perfect record and has proven nothing. TypeSafe’s confidence guidance agrees: “Start with conservative thresholds, test with your own data, and adjust as you observe results.”
The savings floor cuts the other way. If the selector would defer only a sliver of work at a tolerable miss rate, keep running everything.
Step 4: Run shadow until you have seen enough failures, not enough weeks
This is where most shadow periods end too early. Failures are rare, and zero misses in a small sample bounds far less than it feels like it does. With zero false skips among N real failures, the one-sided 95% upper bound on the miss rate is 1 − 0.05^(1/N), roughly 3/N.
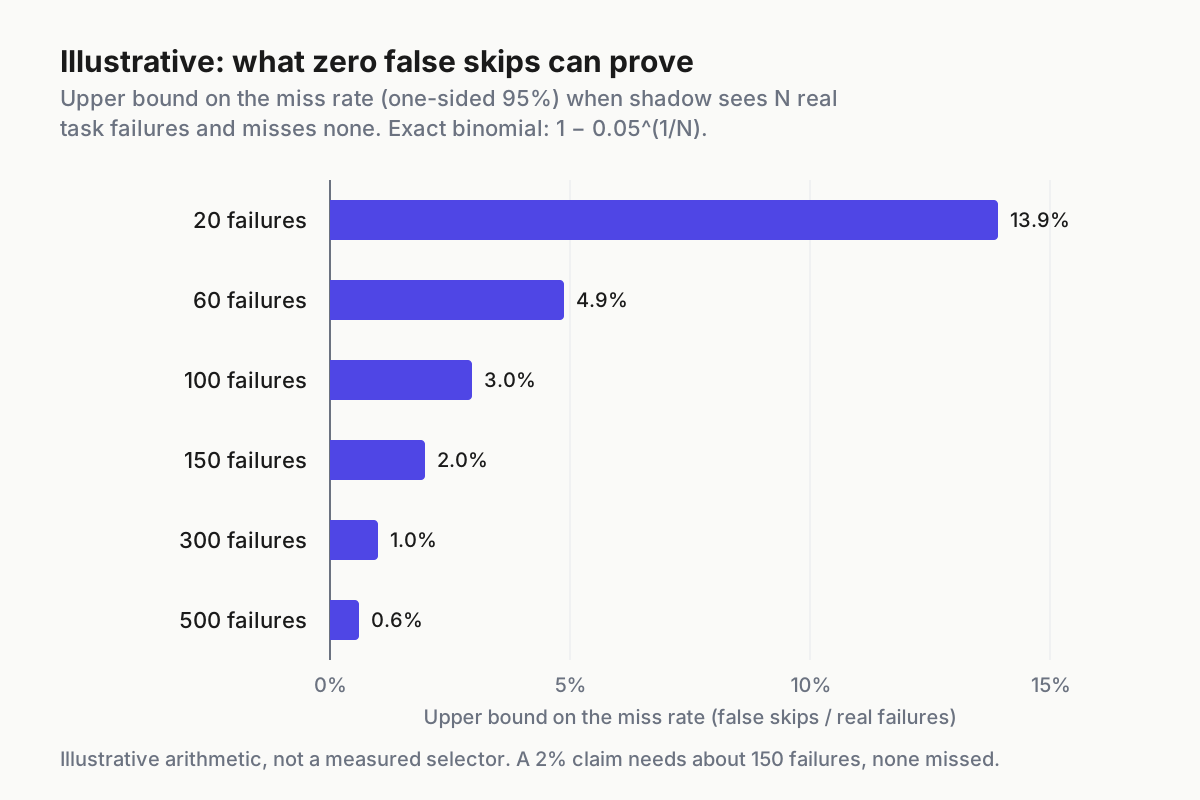 Illustrative arithmetic. Zero misses among 60 real failures still allows a miss rate near 5%; a 1% claim needs about 300.
So shadow exits on a failure count per tier. A repository that sees a dozen genuine task failures a week needs months of shadow to support a 1% budget; accept a looser bound for cheap tasks or keep more of them forced. Tasks that almost never fail cannot be validated one by one; pool them into a tier or force them.
Two kinds of pull request belong in the shadow set on purpose. First, injected ones. A description that argues for its own classification, such as docs-only change, no tests affected, is author-controlled state, often written by an agent, and TypeSafe’s jaggedness page says such text “can move the answer”. Seed shadow with the fixture set from the Jev injection piece and treat any flipped proposal as a finding.
Second, the paths your pipeline treats specially: forks (per the README, forks, missing credentials or consent keep every task without a Jev call), diffs over max-diff-bytes (65,536 by default), and runs where the API is unreachable.
Shadow is cheap to run long. In alga-psa’s live run on one of its own pull requests, selection took “13 requests, ~410k input tokens, under 3 s”: under two cents at the list price of $0.042 per million input tokens, output free. The real cost is the full suite you keep paying for, which was already your bill.
Step 5: Canary on a slice, and catch escapes after merge
jev-ci-selector has two modes, shadow and enforce. Canary is yours to build, which is what the stage step in Step 1 does: one pull request in ten runs in enforce, and the rest stay in shadow and keep feeding the budget.
The canary slice loses its counterfactual, since skipped tasks did not run. Recover it after merge: run the full suite on main for every merge, or nightly, and define an escaped false skip as a task skipped on a canary pull request that fails on the post-merge full run and reproduces. When one merge window bundles several pull requests, a person attributes the failure in the weekly review.
Canary’s real job is the plumbing. Confirm on the slice that:
- Skipped jobs show up as skipped, not missing, and the selector job is itself a required check. The README warns that “a skipped test job alone does not prove selection succeeded.”
- Every forced task runs on every canary pull request.
- Rollback works: set
JEV_SELECTOR_STAGEtoshadow, open a pull request, and check the job summary shows the proposal while every task runs. Time the drill. - A bad API key and an unreachable
api-base-urleach land inbypassedorfallbackand keep every task. The action allows three concurrent requests, 10 seconds each, no retries; the sources we checked do not say what a timeout does to selection. Your drill will.
Promote to enforce when the canary slice has produced no escaped false skips across a window written down in advance, and the shadow majority still meets the budget. Keep the holdback forever: one pull request in twenty is what tells you next quarter that the selector still works.
Step 6: Review every disagreement once a week
Thirty minutes, same people, same agenda: every row where the selector and the full run disagreed, plus every row where the selector did not answer.
| Review item | Question | Possible outcomes |
|---|---|---|
| Every false skip, shadow and escaped | Real miss, flake or infrastructure? | Count it; fix the flake; log infra with a note |
Near misses: failed tasks whose answer sat just above skip-below |
Is the threshold one bad week from a miss? | Tighten skip-below; move the task to forced |
| Proposed skips on PRs whose text argues for the skip | Did the description move the answer? | Add to the injection fixtures; drop the field from state |
bypassed and fallback rows |
Why did the selector not answer? | Fix credentials, timeouts, diff caps |
| Task description edits | Did the question change under the data? | Restart that task’s evidence count |
The last row is the one teams skip. Task descriptions are the questions Jev answers, and the jaggedness page is blunt that jev-1.13 “answers the question you wrote, not the one you meant.” Reword a description and the evidence behind it resets. The Vercel note justifies the fallback row: “Also count timeouts and failed evaluations; they need a defined destination even though they produce no usable prediction.”
Step 7: Write the rollback trigger before you need it
Each trigger names its condition, its action and who may pull it without asking anyone.
| Trigger | Action | Who |
|---|---|---|
| Any false skip on a task that belonged in the forced tier | Stage to shadow today; move the task to forced | On-call |
| Miss-rate bound over budget for any tier | Stage to shadow for that repository; reopen the budget | On-call |
| An escaped false skip reaches a release | Stage to shadow; post-incident review | On-call |
| The response reports a different Jev version | Stage to shadow; re-qualify from zero | Automatic |
| Pinned action SHA bumped with a changed default | Stage to shadow until the diff is reviewed | Automatic |
bypassed plus fallback share over its cap |
Treat as an outage; never count those runs as passes | On-call |
Rollback goes to shadow, never to off. Shadow keeps collecting the evidence you need to climb back.
Keep merge authority out of the selector
The selector decides which checks run on this pull request. It never decides whether the pull request merges. That is the decision seat versus reply seat rule applied to CI: a fast classifier may pick suites for a diff it can see, while the merge verdict stays with required checks, the forced tier, reviewers and the post-merge full run.
No selector output feeds a merge condition directly, and a skipped job is never read as a pass. If your merge rules cannot tell a skipped job from a green one, fix that before enforce.
Where AI CI test selection fails quietly, and the signal for each
The default flips on a bump. Signal: skipped jobs appear while JEV_SELECTOR_STAGE says shadow. Fix: the explicit mode input and the SHA-bump diff.
Fallback reads as a pass. Signal: the fallback share climbs while the skip count stays flat. Fix: fallback keeps every task and counts against max_fallback_share.
Flakes poison the counterfactual. Signal: false skips that do not reproduce on rerun. Fix: the rerun clause and a flake list the review owns.
The pull request argues for its own skip. Signal: skip proposals cluster on PRs whose body claims a docs-only change. Fix: injection fixtures, and state limited to the fields the question needs.
The model moves under the threshold. Signal: model_reported changes. Fix: the automatic rollback and a fresh qualification in shadow.
Rare tasks get skipped on no evidence. Signal: tasks with no failures in the window appear among proposed skips. Fix: pool or force them.
The selector is one more decision seat in the fleet
Nothing here is specific to jev-ci-selector, or to Jev. Any classifier that can skip work, approve a tool call or pick a cheaper model holds a decision seat, and every such seat gets an explicit mode, a pinned version, a counterfactual, a budget, a review and a rollback to shadow. That lives in the operating layer that runs the fleet: the repository variable, the budget file, the join query, the half hour on the calendar.
The tools will keep moving their defaults; this one moved in ninety minutes on a Sunday night. Your ladder is the part that stays put.
FAQ
Does jev-ci-selector run in shadow mode by default?
No. Since PR #4 merged on Sep 20, the mode input defaults to enforce at both the v0.1.0 tag and main, even though the repo description still promises shadow mode by default. Set mode: shadow yourself and pin the action to a full commit SHA, so a later bump cannot change which tests run.
How long should I run a CI test selector in shadow mode?
Until each tier has seen enough real failures, not a fixed number of weeks. With zero false skips among N real failures, the one-sided 95% upper bound on the miss rate is roughly 3/N. Zero misses in 60 failures still allows a miss rate near 5%, and a 1% claim needs about 300.
Sources
- guilhem/jev-ci-selector — description and README on
main, Sep 21, 2026 - jev-ci-selector action.yml on main — inputs, defaults and outputs
- jev-ci-selector PR #4 — merged Sep 20, 2026, 21:36 UTC
- jev-ci-selector v0.1.0 action.yml — defaults at the tag
- jev-ci-selector v0.1.0 release — published Sep 20, 2026, 23:09 UTC
- Nine-Minds/alga-psa PR #3448 — shadow-mode Jev test selection, opened Sep 20, 2026
- TypeSafe: Models — aliases, pinning, pricing
- TypeSafe: Confidence — thresholds tested on your own data
- TypeSafe: Jev 1.13 jaggedness — adversarial state, literal questions
- Vercel: Jev probabilities and decision thresholds — denominators, timeouts, failed evaluations